Demo video. Cosh-DiT generates co-speech gesture videos with expressive faces and natural, smooth gestures that follow the rhythm of the speech.
Co-speech gesture video synthesis is a challenging task that requires both probabilistic modeling of human gestures and the synthesis of realistic images that align with the rhythmic nuances of speech. To address these challenges, we propose Cosh-DiT, a Co-speech gesture video system with hybrid Diffusion Transformers that perform audio-to-motion and motion-to-video synthesis using discrete and continuous diffusion modeling, respectively. First, we introduce an audio Diffusion Transformer (Cosh-DiT-A) to synthesize expressive gesture dynamics synchronized with speech rhythms. To capture upper body, facial, and hand movement priors, we employ vector-quantized variational autoencoders (VQ-VAEs) to jointly learn their dependencies within a discrete latent space. Then, for realistic video synthesis conditioned on the generated speech-driven motion, we design a visual Diffusion Transformer (Cosh-DiT-V) that effectively integrates spatial and temporal contexts. Extensive experiments demonstrate that our framework consistently generates lifelike videos with expressive facial expressions and natural, smooth gestures that align seamlessly with speech.
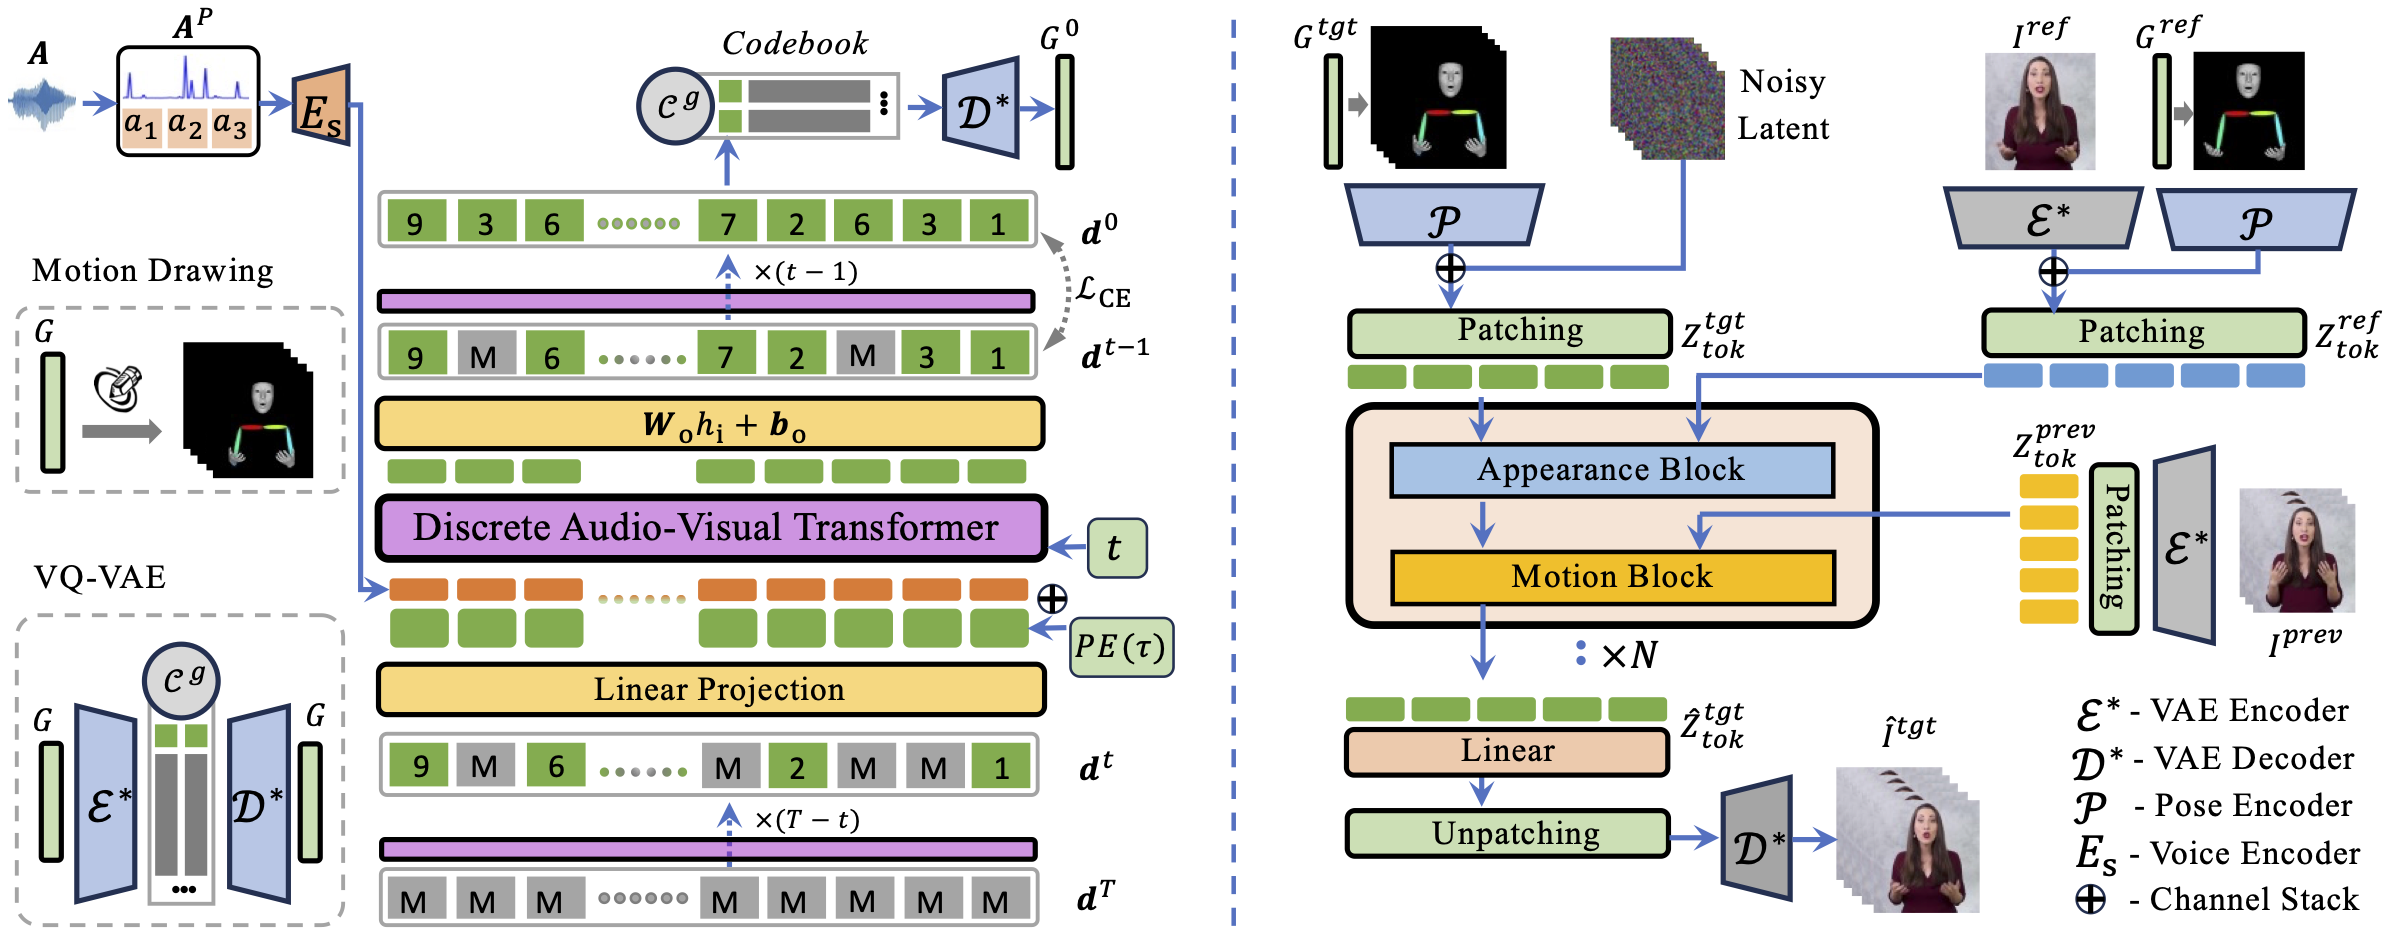
Framework. Left: Cosh-DiT-A, a discrete audio-visual Diffusion Transformer, predicts gesture tokens from speech. VQ-VAEs learn the codebook that jointly encodes upper body, face and hand motion. Right: Cosh-DiT-V, a visual Diffusion Transformer with appearance and motion blocks, renders video frames from the generated motion, a reference image and the previous frames.
@article{sun2026coshdit,
title = {Cosh-DiT: Co-Speech Gesture Video Synthesis via Hybrid Audio-Visual Diffusion Transformers},
author = {Sun, Yasheng and Xu, Zhiliang and Zhou, Hang and Guan, Jiazhi and Yang, Quanwei
and Wang, Kaisiyuan and Liang, Borong and Li, Yingying and Feng, Haocheng
and Wang, Jingdong and Liu, Ziwei and Koike, Hideki},
journal = {International Journal of Computer Vision},
volume = {134},
number = {3},
pages = {85},
year = {2026},
doi = {10.1007/s11263-026-02752-z},
url = {https://doi.org/10.1007/s11263-026-02752-z}
}